Gem 最近在看 stimulusreflex , 这玩意对后端真是友好阿

stimulusreflex 是我发现的对后端及其友好的一种前后端解决方案了
前端解决方案,现在很多了,老的 SJR 不说了,
新的 跟 rails 进一点的算 stimulus, 但是要操作 dom, 感觉比较繁琐
引入 vue 或者 react, 虽然可以不操作 dom, 只需要注重 data 就可以了,但是写完前端又去写后端的接口,特别繁琐
而 stimulusreflex 就正好解决了这个问题,
只需要一点代码,就可以轻松完成前后端的绑定,交互
这里展示它官方的一个例子
<a href="#"
  data-reflex="click->CounterReflex#increment"
  data-step="1"
  data-count="<%= @count.to_i %>"
>Increment <%= @count.to_i %></a>
class CounterReflex < StimulusReflex::Reflex
  def increment
    @count = element.dataset[:count].to_i + element.dataset[:step].to_i
  end
end
整个代码就结束了。没有 js 代码,这货就能正确的处理 点击,传到后端,后端处理,再返回渲染出新的请求,有点意思
更有意思的是,与正常的发起 ajax 请求不同,这玩意是通过 websocket 来传输事件和接受返回结果的
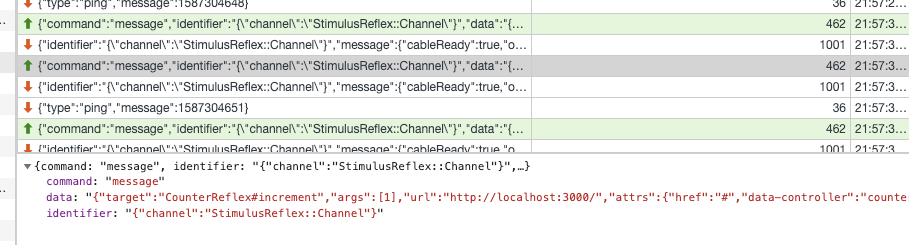
这里是 官方的一些示例
http://expo.stimulusreflex.com/demos
希望能帮助一些 受困于 vue react 的开发者们

 hooopo
回复
stimulusrelex 基于 stimulus 和 websocket
stimulus 本身跟 react 之类的并无冲突,直接可以用
我用 react 其实就是懒得搞 ui
Rails 原生的 websocket 比较弱,这种全靠 websocket 的框架还是观望一下比较好(实在忍不住可以用 phoenix live view)
看过Samuel Williams的 Ruby 处理百万 websocket 连接The Journey to One Million by Samuel Williams后一度对 Ruby 在稍微高一点的并发场景产生了幻想。
Samuel Williams 主推的是基于Fiber的Async做 ruby 的 websocket server,然而 Rails 团队似乎并没有打算用 Aysnc https://github.com/rails/rails/issues/35657
关于 websocket 另一条路是用 Anycable,用 golang 或者 erlang 做 websocket server,再通过一另一个 gRPC 服务跟 Rails 应用代码交互。Stimulusrelex 文档上说已经支持 Anycable 了,但是用 Anycable 增加了部署的复杂度,会不会违背了 Stimulusrelex 的初心 
With StimulusReflex, you'll ship projects faster, with smaller teams and re-discover the joy of programming.
另外分享几个事情:
- 好多年前就有一个基于 websocket 渲染的 Ruby web 框架 https://pakyow.com/ ,开发者也不用自己写 js 代码,跟 Rails + Stimulusrelex 体验很像,停更了几年后最近半年突然 release 1.0,用上了 Async,我猜可能是 Async 解决了他们 websocket scale 的问题。
- Anycable 的作者做的benchmark表明,async 并没有比 puma + actioncable 好太多
 。
刚好也在看另外一个项目 chatwoot, 也是基于 websocket
包括我在内,大家都认为 "Rails 原生的 websocket 比较弱 "
但是确实我也不太了解这块应该怎样去做 benchmark , 也不太知道这个极限值 大概是多少
不知道是否有什么有效的方式,能够知道 这个 rails 的 websocket 的极限是多少呢?


看这个 https://github.com/anycable/anycable/blob/master/benchmarks/2018-10-27.md 压测,
8c15g 20k 的连接。
go 的结果是这个, clients: 20000 95per-rtt: 2892ms min-rtt: 3ms median-rtt: 399ms max-rtt: 4639ms
没找到具体的压测脚本,不知道是怎么发压的。
不过中位和最大 rtt,差这么多,感觉有问题啊。。。
而且 20k 的延迟有 5s,性能感觉也堪忧啊。
官方的解释就是 scale 问题就靠 anycable go 来撑了
因为扩展性做的改变不是很大
算能接受吧
另外一个网站同时在线 1w 配 4 台机器也算能解决一部分问题吧
 jicheng1014
回复
怎样去做 benchmark
要看你们的场景是什么样了,同时在线有多少人,大约会有多少 qps。然后写脚本,模拟这些连接和请求。
至于 4 台行不行,还得压压看。
piecehealth
回复
请教过一个问题,有压测过 actioncable 和 phonex 的 pub/sub 吗?比价好奇两种性能的差距,搜了一下,没找到相关的对比。。。
看了你分享的压测,感觉 go 的实现,也不是很好。。。

 yfractal
回复
可以看一下 https://hashrocket.com/blog/posts/websocket-shootout 粗略比较了各种编程语言/框架 websocket 的指标。
结论
When it comes to websockets, Clojure, Elixir, and Go are all choices that balance great performance with ease of development. NodeJS is in a lower performance tier, but is still good enough for many uses. Rails can only be recommended when part of an existing Rails application with few concurrent clients. C++ offers the best performance, but it is hard to recommend due to the complexity and difficulty of development.
需要指出的是做测试的时候 Rails 6 刚出,puma 还没有用上 nio4r,所以 Rails 支持的连接数看起来弱爆了,但是不代表现在 Rails 的真实水平。
ActionCable 比较大的问题是 broadcast 是基于线程池的,线程池大小默认是 5(可以通过 config.action_cable.worker_pool_size 调整),换句话说一个 puma worker 同一时间只能同时向 5 个 websocket client 发消息 
piecehealth
回复
感谢,这个 clojure 竟然表现不错,不过感觉是占代码少的便宜
然后 elixir 用内存多,感觉可以调一下 min_heap_size,那个用来缓存消息的。
ActionCable 性能渣渣,盲猜,应该是消耗在线程切换了。nio 就是为不用线程模型。然后 RoR 又在这加回来了。。。
也不能用 Fiber 解。这块加 thread pool,我猜是为了避免一次处理时间过长,卡了所有的任务。用 Fiber 没发避免这个问题。
所以还得用 thread pool,不过应该有更好的解法。
还不是很理解,为啥 broadcast 的时候要用 thread pool,因为 io 已经 异步了。如果是接收消息的时候,有线程池,还可以理解。。
yfractal
回复
还不是很理解,为啥 broadcast 的时候要用 thread pool,因为 io 已经 异步了
ActionCable 的实现是在内存里维护一个订阅列表的 hash,key 是 channel,value 是一个订阅者回调 lambda 的 array,
回调 lambda : https://github.com/rails/rails/blob/master/actioncable/lib/action_cable/channel/streams.rb#L146-L154
def worker_pool_stream_handler(broadcasting, user_handler, coder: nil)
  handler = stream_handler(broadcasting, user_handler, coder: coder)

  -> message do
    connection.worker_pool.async_invoke handler, :call, message, connection: connection
  end
end
broadcast 的时候:https://github.com/rails/rails/blob/master/actioncable/lib/action_cable/subscription_adapter/subscriber_map.rb#L36-L45
def broadcast(channel, message)
  list = @sync.synchronize do
    return if !@subscribers.key?(channel)
    @subscribers[channel].dup
  end

  list.each do |subscriber|
    invoke_callback(subscriber, message)
  end
end
invoke_callback最终是上面那段 lambda
-> message do
  connection.worker_pool.async_invoke handler, :call, message, connection: connection
end
worker_pool是一个 thread pool (Concurrent::ThreadPoolExecutor),async_invoke是往 thread pool 里塞任务,任务异步执行,所以遍历 subscribers 时是不会阻塞的,而消息何时向全部 client 发完取决于 thread pool 消化任务是的速度了。而且整个 ActionCable 是公用一个 thread pool 的。
piecehealth
回复
感谢
broadcast 是用来给所有 channel 内的连接发消息的。
这个地方,大体做的事情,就是 encode 和 往 IO 里写。
encode 消耗的是 cpu 资源,用不用线程池意义不大。甚至不用线程池可能更快。
debug 看了下,写 io 的时候,是异步的。线程池也没有意义。
如果没同步 io 操作,线程池意义不大,或者说纯粹的 CPU 计算,线程池其实没啥意义。
整个 ActionCable 是公用一个 thread pool 的
共用线程池不是一个很好的做法。
anycable 已经更新到了 1.0 版本 看着性能还是不错的 10000 个 client 95% 也就 1 秒
clients:  1000    95per-rtt: 196ms    min-rtt:   2ms    median-rtt:  33ms    max-rtt: 252ms
clients:  2000    95per-rtt: 296ms    min-rtt:   2ms    median-rtt:  48ms    max-rtt: 596ms
clients:  3000    95per-rtt: 462ms    min-rtt:   2ms    median-rtt: 101ms    max-rtt: 694ms
clients:  4000    95per-rtt: 670ms    min-rtt:   3ms    median-rtt:  72ms    max-rtt: 1382ms
clients:  5000    95per-rtt: 712ms    min-rtt:   3ms    median-rtt: 101ms    max-rtt: 1526ms
clients:  6000    95per-rtt: 739ms    min-rtt:   3ms    median-rtt:  99ms    max-rtt: 2901ms
clients:  7000    95per-rtt: 745ms    min-rtt:   2ms    median-rtt: 231ms    max-rtt: 2800ms
clients:  8000    95per-rtt: 950ms    min-rtt:   2ms    median-rtt: 173ms    max-rtt: 3109ms
clients:  9000    95per-rtt: 1133ms   min-rtt:   3ms    median-rtt: 185ms    max-rtt: 4084ms
clients: 10000    95per-rtt: 1033ms   min-rtt:   3ms    median-rtt: 248ms    max-rtt: 2671ms
https://github.com/anycable/anycable/blob/master/benchmarks/2020-06-30.md